Avoid the PostgreSQL-to-Kafka dual-write gap with a transactional outbox. A practical walkthrough of Debezium CDC, idempotent consumers, ordering, and recovery.
- Best Practices
Transactional Outbox Pattern with Kafka and PostgreSQL
- Prabhat Kashyap
- October 29, 2026
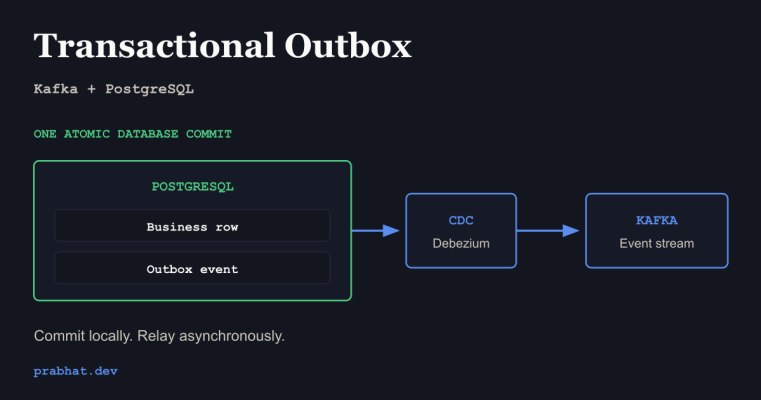
An order is saved in PostgreSQL. The next line publishes OrderCreated to Kafka. Between those two lines, the process dies.
The database says the order exists. The fulfillment service never hears about it. Retrying the HTTP request might create another order, and Kafka producer retries cannot recover a send that never happened.
The transactional outbox pattern makes the business change and the intent to publish an event part of one database transaction. A separate relay delivers that committed event to Kafka. I will use PostgreSQL, Debezium, and Kafka to explain the mechanism, then follow the failure boundary into the consumer.
The examples use a fictional order service. The SQL is intentionally small; the connector settings are an excerpt, not a complete deployment recipe. The important question is which changes commit together, and what a retry does at each boundary.
Why two successful APIs do not make one transaction
Consider this application flow:
saveOrderInPostgres(order);   // transaction commits
publishToKafka(orderCreated); // a separate operation
Each call can be correct in isolation. Their combination has a gap. Once PostgreSQL commits, a Kafka outage, application crash, or network failure can prevent the event from being published.
Reversing the order moves the problem. Kafka can accept the event, then the database transaction can roll back. Consumers act on an order that does not exist. Keeping a database transaction open while calling Kafka also leaves two separate commit decisions, while holding database resources for longer.
A Kafka acknowledgment tells the producer about the Kafka write. It does not commit PostgreSQL. An HTTP timeout is equally inconclusive: a database commit might have succeeded even though the response was lost. These are separate failure domains.
Commit the state and the event intent together
An outbox is an application-owned table containing events to deliver. The request handler inserts the order and its event using the same PostgreSQL transaction and connection. It does not publish to Kafka on that request path.
If the transaction rolls back, neither row is committed. If it commits, both are durable under the database’s configured durability guarantees. Kafka can be unavailable at that moment. Delivery waits for the relay to recover, provided the required history remains available.
This changes the synchronous guarantee: the response can say the order was accepted, not that every downstream service has processed it. The system is eventually consistent across services. The Debezium outbox introduction describes this local transaction and asynchronous publication model.
Change data capture (CDC) reads database changes and forwards them elsewhere. PostgreSQL records changes in its write-ahead log, or WAL. Debezium’s PostgreSQL connector uses logical decoding to capture committed changes. Its outbox event router transforms an outbox row into an application event. Kafka stores that event for consumers.
The outbox provides the event contract; CDC provides the transport mechanism. Capturing every change to the orders table directly would expose storage changes, which are not necessarily the domain events consumers need.
A PostgreSQL schema and transaction
Start with a business table and the outbox columns expected by Debezium’s router:
CREATE TABLE public.orders (
    id uuid PRIMARY KEY,
    status text NOT NULL,
    version bigint NOT NULL
);

CREATE TABLE public.outbox_event (
    id uuid PRIMARY KEY,
    aggregatetype varchar(255) NOT NULL,
    aggregateid varchar(255) NOT NULL,
    type varchar(255) NOT NULL,
    payload jsonb NOT NULL,
    created_at timestamptz NOT NULL DEFAULT now()
);
Here, an aggregate is the business entity whose changes need an ordered history: one order. The outbox event ID identifies an event; the aggregate ID identifies the order. They serve different purposes.
Create an order and its event in one transaction. Fixed UUIDs make this example easy to follow. In an application, generate the identifiers once for the operation and pass values as bound parameters.
BEGIN;

INSERT INTO public.orders (id, status, version)
VALUES ('11111111-1111-4111-8111-111111111111', 'created', 1);

INSERT INTO public.outbox_event
    (id, aggregatetype, aggregateid, type, payload)
VALUES (
    '22222222-2222-4222-8222-222222222222',
    'orders',
    '11111111-1111-4111-8111-111111111111',
    'OrderCreated',
    '{"event_id":"22222222-2222-4222-8222-222222222222",
      "event_type":"OrderCreated",
      "schema_version":1,
      "order_id":"11111111-1111-4111-8111-111111111111",
      "aggregate_version":1}'::jsonb
);

COMMIT;
The payload deliberately repeats the event ID and event type. That gives the JSON value a usable envelope even when a downstream tool does not preserve Kafka headers. Keep these values consistent with their corresponding outbox columns. schema_version describes the payload format; aggregate_version describes the entity’s change sequence.
The order and event must be written through the same transaction. A second connection, an asynchronous callback after commit, or an ORM hook with a separate transaction reintroduces the gap.
The application treats event rows as immutable. It inserts new events instead of changing old payloads. It also needs command idempotency: an API retry must not create a new logical order or a second event for an already completed command. Consumer deduplication cannot repair that mistake.
Route outbox inserts to Kafka with Debezium
The PostgreSQL connector needs wal_level=logical, a database account with the required replication and table permissions, enough replication slots and WAL senders, and a publication that includes the outbox table. A deployment identity can create the publication:
CREATE PUBLICATION commerce_outbox_pub
FOR TABLE public.outbox_event;
Then configure the connector. This excerpt shows the capture and routing settings. Supply the database connection, secret management, TLS, Kafka Connect worker configuration, connector installation, and access controls for your environment. Check the PostgreSQL connector documentation against the version you deploy.
{
  "connector.class": "io.debezium.connector.postgresql.PostgresConnector",
  "plugin.name": "pgoutput",
  "topic.prefix": "commerce",
  "slot.name": "commerce_outbox",
  "publication.name": "commerce_outbox_pub",
  "publication.autocreate.mode": "disabled",
  "table.include.list": "public\\.outbox_event",
  "snapshot.mode": "initial",
  "transforms": "outbox",
  "transforms.outbox.type": "io.debezium.transforms.outbox.EventRouter",
  "transforms.outbox.predicate": "IsOutbox",
  "transforms.outbox.table.expand.json.payload": "true",
  "transforms.outbox.table.fields.additional.placement": "type:header:eventType",
  "predicates": "IsOutbox",
  "predicates.IsOutbox.type": "org.apache.kafka.connect.transforms.predicates.TopicNameMatches",
  "predicates.IsOutbox.pattern": "commerce\\.public\\.outbox_event",
  "key.converter": "org.apache.kafka.connect.storage.StringConverter",
  "value.converter": "org.apache.kafka.connect.json.JsonConverter",
  "value.converter.schemas.enable": "false"
}
table.include.list matches schema.table. The predicate matches the original CDC topic, commerce.public.outbox_event, before the router renames it. This keeps the outbox transform away from heartbeat or transaction metadata records. See Debezium’s selective transformation documentation.
With the router defaults and the JSON expansion setting above, the example produces:
topic:            outbox.event.orders
key:              11111111-1111-4111-8111-111111111111
header id:        22222222-2222-4222-8222-222222222222
header eventType: OrderCreated
value:            the expanded JSON payload from the row
The router uses aggregatetype for topic routing, aggregateid for the Kafka key, and payload for the value. JSON expansion is explicit because it is disabled by default. The extra placement setting exposes type as an eventType header. Application updates to event rows are invalid; cleanup deletes are filtered. These behaviors are documented in the Outbox Event Router reference.
Choose the topic’s replication, retention, minimum in-sync replicas, and producer acknowledgment policy deliberately. The outbox does not make a weakly configured broker durable. The example assumes a regular event topic, not a compacted topic intended to preserve only the latest record per order.
Delivery guarantees stop at specific boundaries
This design assumes at-least-once CDC delivery: after recovery, an event may appear again. A failure can happen after Kafka accepts a record but before the connector’s progress is durably recorded. PostgreSQL can also resend recent logical changes after a server crash. Its logical decoding documentation explicitly assigns duplicate handling to decoding clients.
Kafka producer idempotence suppresses duplicates from producer retries within its supported protocol guarantees. It does not identify every new send of the same business event, and it does not include a consumer’s PostgreSQL transaction. See the Kafka producer configuration reference.
Debezium also supports optional Kafka Connect source exactly-once delivery for supported connectors, including PostgreSQL. That requires coordinated worker and connector configuration and consumers that respect transaction isolation. It is not assumed here, and it still does not atomically include a downstream database effect. The Debezium exactly-once guide defines that narrower boundary.
Keep a stable event ID, and make a repeated event safe for each consumer. Reliability comes from specifying the boundaries, not attaching an end-to-end “exactly once” label to the whole pipeline.
Make the consumer’s database effect idempotent
Suppose a metrics consumer increments an order counter. Incrementing twice is incorrect. Store an event receipt, sometimes called an inbox entry, in the consumer’s database. Commit the receipt and the metric change together.
CREATE TABLE public.processed_event (
    consumer_name text NOT NULL,
    event_id uuid NOT NULL,
    processed_at timestamptz NOT NULL DEFAULT now(),
    PRIMARY KEY (consumer_name, event_id)
);

CREATE TABLE public.order_statistics (
    metric text PRIMARY KEY,
    value bigint NOT NULL
);
The primary key includes the logical consumer name. Two different consumers may legitimately process the same event. This name is stable across replicas and restarts; it is not a process ID.
For a validated OrderCreated event, execute:
BEGIN;

WITH first_delivery AS (
    INSERT INTO public.processed_event (consumer_name, event_id)
    VALUES ('orders-metrics-v1', '22222222-2222-4222-8222-222222222222')
    ON CONFLICT (consumer_name, event_id) DO NOTHING
    RETURNING event_id
)
INSERT INTO public.order_statistics (metric, value)
SELECT 'orders_created', 1 FROM first_delivery
ON CONFLICT (metric) DO UPDATE
SET value = order_statistics.value + EXCLUDED.value;

COMMIT;
RETURNING supplies a row only for the first receipt. The counter insert or increment therefore runs once. A duplicate event produces no new receipt and no counter change. If the statement or transaction fails, both changes roll back. PostgreSQL’s unique constraint and ON CONFLICT behavior arbitrate concurrent attempts without a separate check-then-insert race.
The surrounding consumer loop is equally important. This is pseudocode, with database details supplied by the transaction above:
for each record, in partition order:
    validate event type, schema version, and event ID
    run receipt + counter transaction with bound parameters
    if the database commit fails or its result is unknown:
        retry without advancing the Kafka offset
    otherwise:
        commit the next offset for this partition
If the process crashes after the database commit but before the offset commit, Kafka can deliver the event again. The receipt prevents the second increment. If the offset were committed first, a crash could permanently skip the database effect.
Disable automatic offset commits for this flow. Process records sequentially within each partition, or track contiguous completion before advancing its offset. Never commit past unfinished records. Rebalances and offset-commit failures can cause redelivery, so the database receipt remains necessary.
This protects a database effect inside that transaction. Sending email or calling a payment API inside it is a separate side effect. Use the recipient’s idempotency key, another outbox, or a workflow designed for that boundary. A local rollback cannot unsend an email.
Ordering requires more than a Kafka key
Kafka orders records within a partition. A stable order ID as the key keeps one order’s events together under a stable partitioning scheme. It does not establish a global order across every order, topic, or consumer. Kafka’s design documentation explains the partition and processing guarantees.
Three application decisions still matter:
- Serialize changes to an order. Use row locking or optimistic concurrency, and write the next aggregate version and event in the same transaction. A timestamp or UUID is not a business sequence.
- Preserve order through processing. Parallel work within a partition and retry topics can let later events overtake an earlier failed one. Decide whether a consumer must pause, buffer, or reject a version gap.
- Plan partition changes. Increasing a topic’s partition count can remap a key. An ordering-sensitive migration needs a cutover plan.
A duplicate event ID and an out-of-order aggregate version are different conditions. Deduplication handles repetition. A projection that requires sequential state transitions must also define what happens when version 4 arrives before version 3.
CDC or a polling relay?
Debezium is one relay implementation. A polling relay can query pending outbox rows and publish them to Kafka. That may be a reasonable choice when the team can operate a small worker more easily than a CDC pipeline.
Polling has the same acknowledgment boundary: marking an event delivered before Kafka acknowledges risks loss; marking it afterward leaves a duplicate window if the worker crashes. Concurrent SKIP LOCKED workers can also publish one order’s later event first unless the relay explicitly preserves aggregate order.
I would choose based on operational ownership, expected volume, acceptable delay, and ordering requirements. CDC avoids repeated pending-row scans, but adds replication slots, connector state, snapshots, and WAL retention to the things the team must understand. Neither choice removes consumer idempotency.
The production work is recovery and retention
Watch retained WAL, not just connector health
A disconnected replication slot can retain WAL. The database can keep serving requests while disk usage grows. Monitor the slot’s restart_lsn, acknowledgment progress, WAL status, and database free space, alongside connector errors, event latency, and consumer lag. PostgreSQL exposes slot state in pg_replication_slots.
max_slot_wal_keep_size can bound retained WAL, but hitting that limit can remove history the connector still needs. Unlimited retention risks filling disk; a finite cap requires a tested recovery plan. Neither is a substitute for alerts. See the replication configuration reference.
Define what can be replayed
The initial snapshot can emit retained outbox rows. A new slot, lost connector offsets, or a rebuild can change what is replayed. Deleted outbox history cannot be reconstructed by a fresh snapshot. Test database failover and connector recovery with the actual versions and managed service you run.
Outbox cleanup needs verified capture progress and an explicit recovery window. “Delete everything older than one hour” is unsafe if the relay can be down for longer. Conversely, retaining every event forever turns a transport table into an unmanaged archive. Batch cleanup, account for vacuum and index growth, and keep audit history separately if the product needs it.
Deduplication retention has the same dependency: deleting receipts allows an old replay to apply effects again. Keep receipts for the supported replay horizon, or rebuild into an isolated target with a new, deliberate consumer identity. A new identity against the existing counter would increment it again.
Treat event schemas as contracts
Validate event type and schema version before applying effects. Prefer compatible additions, coordinate breaking changes, and avoid filling the payload with an entire database row. Publish the facts consumers need. Decide how malformed or unsupported events are quarantined, alerted, and replayed; silently skipping them makes the pipeline appear healthier than the product is.
An outbox removes Kafka availability from the immediate write path, but not forever. A prolonged outage can exhaust storage. Define the point at which to alert, throttle writes, or reject new work instead of assuming the backlog is unbounded.
Test the crash windows before trusting the pipeline
A happy-path integration test proves only that the components can connect. I would also test these failures:
- Rollback the request transaction. Neither the order nor its outbox event should remain.
- Stop the relay while orders commit. Events should arrive after restart within the supported retention window.
- Restart after a Kafka write near connector checkpointing. Repeated event IDs must be safe.
- Crash the consumer after its database commit. Redelivery must leave the counter unchanged.
- Fail the consumer’s business statement. The receipt must roll back, and the offset must not advance.
- Replay old data and trigger a rebalance. Check duplicates, ordering, and offset progress.
- Exercise slot loss, failover, and cleanup during a long outage. Verify which data can be recovered and how missing history is detected.
Write down the expected database rows and offset after each drill. Recovery should be repeatable enough to run during an incident without guessing.
When I would use the pattern
Use an outbox when a committed database change must eventually produce an event and a missing event would leave downstream behavior incorrect. It fits order workflows, projections, integrations, and other asynchronous work derived from committed state.
It adds an event table, relay ownership, retention policy, and consumer recovery logic. A local database transaction is simpler when all required work belongs in the same database. An outbox also does not provide immediate consistency across services or coordinate a multi-service business transaction by itself.
The core rule is small: commit business state and event intent together. Then make delivery recoverable and repeated processing safe. PostgreSQL supplies the local atomic boundary. Debezium carries committed events to Kafka. Each consumer owns its own transaction, idempotency, ordering, and replay policy.
For related backend design notes, browse Best Practices. For more PostgreSQL content, see PostgreSQL 19 SQL/PGQ: Graph Queries, a separate look at graph queries and their version-specific support.
Related
Share
Prabhat Kashyap
Senior Technical Architect at HCLTech · working with Leonteq Security AG
I have 10+ years of experience building distributed systems and fintech platforms. I write about practical, non-obvious engineering details that official documentation often skips.
Newsletter
Get new engineering deep dives
Scala, JVM, AI, and backend systems. I send practical articles when there is something worth reading.
Join the newsletter